Access design: four search modes so the AI doesn't just confirm me
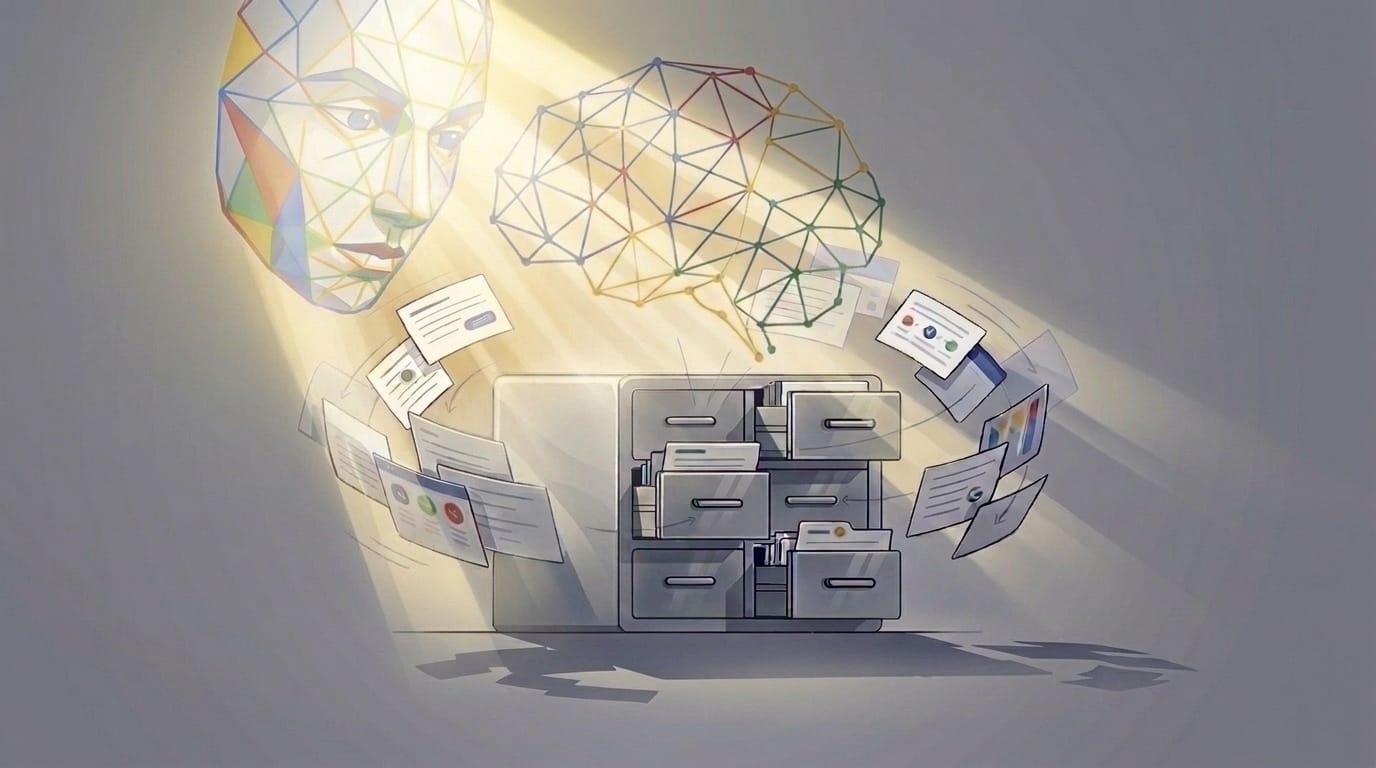
When I look for a note, I usually find what I expected. For a filing system, that's a seal of quality.
For a thinking process, it's a problem.
Thinking makes leaps. It places things side by side that never sat side by side in a folder. This is exactly where it is decided what an LLM is in my knowledge work: a better search bar — or a tool that expands my space of perception.
In the first part I described why AI-supported knowledge work can lead to a flattening. A model finds the plausible, formulates the plausible, and thereby moves easily within the order my system already carries.
That left a practical question open: how would access have to be designed so that the AI doesn't merely reproduce my perspective? What follows is not a finished procedure. It's my working model for a controlled open search space.
I call this working model access design (Zugriffsdesign). It governs three things: which material the AI may search in, by which criteria it selects findings, and at which point my interpretation begins.
Access design is therefore more than a good prompt. It's the architecture between my body of knowledge, the searching tool, and my own work of judgement.
The dilemma: my system condenses meaning
My second brain is not a neutral data store. It's sedimented perspective. I selected, formulated, linked, named, and filed. Each of these acts was a judgement.
That's the strength of the system. And the starting point of a problem.
When retrieving, an LLM searches for semantic proximity. When formulating, it searches for linguistic plausibility. Both movements point in the same direction: towards the obvious.
If I apply both to a system that is already condensed, the condensation takes effect twice. It preferentially finds what fits anyway — and formulates from it what fits again.
An uncomfortable consequence follows. A good access design has to occasionally disadvantage precisely what fits best. For knowledge work, relevance isn't always the right ranking criterion.
Context-open, not context-free
One misunderstanding first: associative thinking is not context-free. Context-freeness would be arbitrariness — random notes, random leaps, no yield.
Associative thinking is context-open. The present context doesn't fully determine which connection becomes possible next.
That's a tangible requirement for the technology. I don't need less context. I need mechanisms that deliberately go beyond the context at hand.
Three relational levels
Before I formulate rules, I distinguish where a connection can come from in the first place.
- Explicit relations — links, tags, and relations I set myself. They are vetted. Their drawback: they only show what I have already understood.
- Implicit relations — semantic or structural similarity, as a vector search finds it. They are probable, but rarely surprising.
- Exploratory relations — deliberately distant, contradictory, or weakly related findings. They are risky, and they are the only level on which a genuine leap can occur.
Most AI setups use levels one and two. Level three has to be ordered explicitly, otherwise it never arrives.
Four retrieval modes with instruction sentences
This is the core of access design: not one mode, but four, deliberately chosen.
- Relevance — “Stay within my perspective”. Instruction: “Find notes that directly complement, sharpen, or support my current question.” The default mode. Useful when I want to act. Risky when I want to think.
- Contradiction — “Attack my perspective”. Instruction: “Search my collection for notes, quotes, and experiences that contradict my current position, and name the contradiction without smoothing it over.”
- Distant analogy — “Leave my field of meaning”. Instruction: “Ignore thematic proximity. Find notes from distant fields that contain a similar structure or tension.”
- Serendipity — “Surprise me”. Instruction: “Pull in three notes that are neither semantically similar to nor linked with my question. Only afterwards check whether a productive connection can be constructed.”
The principle behind modes two to four: controlled distance with a subsequent test of meaning. First open the search space, then judge — not the other way round.
The cycle of insight in seven stages
The modes need a sequence, otherwise it stays a random generator. I work with seven stages. Each has an action sentence for me and an assignment for the tool.
| Stage | My action sentence | Assignment for the tool |
|---|---|---|
| 1 Asking | I name what I'm currently thinking about. | Restate my question in your own words. |
| 2 Finding | I let what exists surface. | Show what's relevant and my existing links. |
| 3 Breaking | I open the search space deliberately. | Switch to contradiction, distant analogy, and serendipity. |
| 4 Juxtaposing | I look at what doesn't fit together. | Place findings side by side without reconciling them. |
| 5 Interpreting | I check whether the relation means something. | Show the relation, don't decide for me. |
| 6 Condensing | I formulate the insight. | Proofread, name the weak spots. |
| 7 Writing back | I decide what becomes part of the system. | Document the confirmed connection. |
The movement is a circle: meaning → relation → break in meaning → interpretation → new meaning.
That's closer to scientific work than to searching. I have a hypothesis, I observe, I interpret — and confirm or discard.
Metadata: describing or interpreting?
For the rules to take hold, they have to be in play early. Part of that can be laid down in advance: as metadata on the material and as mode rules in the assignment.
One distinction is decisive here.
Descriptive metadata keep the space open: point in time, source, project context, explicit links, the degree of certainty of a statement, original text or my own interpretation.
Interpretive metadata narrow it: “relevant for X”, “means Y”, “belongs to theory Z”. They preserve today's structure of meaning — and block tomorrow's leap.
My rule from this: descriptively rich, interpretively sparing, and always dated. A reading from 2023 must not serve as a sorting criterion in 2026.
What the tool can do and what it can't
An LLM can compute relations. It can make them linguistically plausible. It doesn't follow that the relation has meaning for me.
That's why I deliberately don't frame serendipity as a machine achievement: it doesn't arise because a machine discovers meaning, but because something unexpected enters my space of perception and I recognise meaning in it.
My goal is therefore not a context-free second brain. My goal is a system that keeps its own context open to irritation.
Objections and answers
1. “Four modes are four prompts. That's manual labour, not a system.”
For now, yes. But modes can be stored as templates and called up per task. The effort sits once in the design, not in every request.
2. “Ordered chance is not chance.”
Correct, it's controlled distance. The difference from a genuinely chance find remains. But the find at the bookshelf was never accidental either — I had filled that shelf myself.
3. “If the tool finds and formulates the connection, you're outsourcing exactly the thinking your system is supposed to foster.”
The strongest objection. With the selection of findings, the AI already takes over part of my thinking process. That selection isn't neutral. So it isn't enough for me to write only the last sentence myself.
I need to be able to see where a find comes from, in which mode it was selected, and whether a connection is evidenced in the material or merely suggested by the model. The AI may expand my space of perception. But it must not invisibly decide which perspective becomes dominant within it.
My boundary therefore stays methodically visible: finding and proofreading is for the tool. Interpreting and writing back stay with me. Findings are displayed with their provenance, first placed side by side, and not automatically absorbed into my knowledge system.
4. “Contradiction from your own collection is toothless.”
Fair. Whoever only queries their own notes gets contradiction in their own language. That's why outside sources from my reading collection belong explicitly in the search space.
Conclusion
My goal is not a context-free second brain. Nor do I want a system that keeps me busy with random finds and declares every distant similarity an insight.
I want a knowledge system that stays open to irritation: reliable when I want to act, and open enough when I want to think.
The AI can select findings and propose relationships. Whether an insight emerges from that only shows in my examination — and in what I subsequently write back in my own words.
Three sentences to take away:
- For AI-supported knowledge work, it isn't enough to provide as much context as possible. Search rules and access boundaries matter too.
- Four modes and seven stages open the search space without invisibly handing interpretation over to the tool.
- For my knowledge work, I treat the LLM as a tool for relations. A connection only becomes my insight once I examine and situate it.
That's how I understand digital workplace design today: a cognitive working environment that removes friction where I want to act — and creates productive friction where I want to think.
The foundation for this access design is a system that holds. I show you how to build it in the Roadmap to the Second Brain,
Sources
Own foundations
- mindOS Roadmap 2026 – Baue dein Second Brain
- Digital Workplace Design — the learning and working environment as a design task
- Tiago Forte: The Master Prompt 2.0 — Live Session · Building a Second Brain / PARA
Flattening: homogenisation of outputs
- Doshi & Hauser (2024): Generative AI enhances individual creativity but reduces the collective diversity of novel content. Science Advances.
- Anderson, Shah & Kreminski (2024): Homogenization Effects of Large Language Models on Human Creative Ideation. C&C '24.
- Padmakumar & He (2024): Does Writing with Language Models Reduce Content Diversity? ICLR 2024.
- Tilburg University (2026): Does generative AI make us think alike? A systematic review and three-level meta-analysis — 19 studies, 61 effect sizes.
- Sourati, Ziabari & Dehghani (2026): The homogenizing effect of large language models on human expression and thought. Trends in Cognitive Sciences.
- Sourati et al. (2025): The shrinking landscape of linguistic diversity in the age of large language models.
Flattening: bodies of knowledge and models
- Wright et al. (2025): Epistemic Diversity and Knowledge Collapse in Large Language Models.
- Shumailov et al. (2024): AI models collapse when trained on recursively generated data. Nature 631, 755–759.
Flattening: the effect on ourselves
- Kosmyna et al. (2025): Your Brain on ChatGPT — Accumulation of Cognitive Debt. MIT Media Lab, preprint.
- Lee et al. (2025): The Impact of Generative AI on Critical Thinking. CHI '25.
- Gerlich (2025): AI Tools in Society: Impacts on Cognitive Offloading and the Future of Critical Thinking. Societies 15(1).
Counter-evidence and levers
- Wan & Kalman (2025): Diverse AI Personas Can Mitigate the Homogenization Effect in Human-AI Collaborative Ideation. Computers in Human Behavior: AI.
And receive regular updates from my digital garden.